广告
加载中

吃掉书的AI 以及翻书的那只手

张睿 2026-08-07 11:48
张睿 2026/08/07 11:48

邦小白快读

EN
全文速览

本文曝光了AI公司Anthropic的秘密项目巴拿马计划,梳理了事件的来龙去脉和引发巨大争议的原因,核心干货如下

1. 事件基本信息:巴拿马计划2024年初启动,预算达数千万美元,Anthropic通过二手书商批量采购数百万册2022年前出版的纸质书,扫描后全部销毁,目前已累计销毁约200万册,事件曝光后在X平台引发超两千万浏览,近四千条批评声音。

2. 事件争议点:Anthropic此举本质是为了获取大模型训练语料,既钻了美国法律的空子,通过销毁实体书获得“合理使用”的判定,又损害了文化传承,销毁的多是流通量极少的孤本、绝版冷门书;对比早年Google的图书扫描项目,两种做法凸显了AI发展中人文价值的缺失。

本次事件对涉及AI、文化内容领域的品牌商有多方面的参考价值,核心干货如下

1. 版权合规风险提示:当前AI版权已经成为全球高发的法律纠纷,截至2026年5月,全球在审AI版权相关诉讼共112起,近八成集中在美国,Anthropic此前就因使用盗版电子书训练被判赔偿15亿美元和解金,品牌布局AI业务必须提前做好版权合规,规避巨额赔偿风险。

2. 品牌声誉提示:Anthropic秘密销毁图书的行为引发公众大规模批评,说明公众非常重视文化传承,品牌开展相关业务不能只看商业利益,要兼顾公众文化情感,否则会对品牌声誉造成不可逆的损害。

3. 品牌建设启示:公众认可数字化过程中的人文价值,品牌可以挖掘人文价值打造品牌好感,获得公众认同。

本次事件给二手书卖家带来了明确的机会和风险提示,核心干货如下

1. 市场机会:AI大模型公司对长尾冷门纸质书有大规模批量采购需求,这类书籍原本在二手市场流通量极低,大额订单能给卖家带来直接的经济收益,卖家可以针对性整合冷门学术专著、地方史料、小众技术手册等稀缺资源,对接大模型公司的采购需求,开拓新的营收渠道。

2. 风险提示:当前该采购行为的最终用途是扫描后销毁,已经引发了大规模的舆论争议,批评其损害文化传承,未来很可能出台相关管制政策,卖家需要密切关注政策动向,平衡商业收益和行业伦理,规避舆论和政策风险。

本次事件给图书加工、数字化相关工厂带来了新的商业机会和发展启示,核心干货如下

1. 新商业机会:AI大模型公司对实体书批量数字化加工有旺盛需求,整个流程需要液压切书脊、高速扫描、粉碎销毁等多个加工环节,目前已经出现千万美元预算、百万级处理量的项目,相关工厂可以开拓对应业务线,对接大模型公司的需求,获得新的增长空间。

2. 升级启示:和传统图书馆扫描需要人工处理旧书珍本不同,该业务对自动化加工效率要求很高,不需要人工翻页环节,工厂可以推进自动化流水线升级,提升大规模批量处理能力,适配客户需求。

3. 风险提示:该业务涉及文化争议,工厂承接业务需要确认合规性,跟进后续政策变化,规避潜在风险。

本次事件暴露了AI大模型行业的痛点和发展新趋势,对相关数字化、AI服务商有不少参考,核心干货如下

1. 行业痛点:大模型公司对高质量稀缺语料有极其旺盛的需求,但版权合规问题始终是行业瓶颈,传统的授权模式成本高、效率低,难以满足大模型对海量语料的需求,行业急需新的合规解决方案。

2. 发展趋势:目前大模型公司已经开始绕过现有线上版权框架,通过线下采购实体书、扫描后销毁的方式获取合法语料,未来对实体书批量数字化加工的需求会持续增长,市场空间较大。

3. 业务方向:服务商可以针对性开发自动化实体书扫描加工解决方案,也可以探索合法合规的语料授权交易模式,解决行业痛点,开拓新的业务增长点。

本次事件给开展AI相关业务的平台商带来了风险规避和业务发展的多重启示,核心干货如下

1. 风险规避:版权风险是当前AI平台最大的法律风险,全球超八成AI版权诉讼集中在美国,已有企业为此付出15亿美元和解金,平台布局AI训练业务必须提前做好版权合规布局,避免陷入巨额赔偿诉讼。

2. 业务机会:大模型公司对稀缺语料的旺盛需求催生了新的交易场景,平台可以搭建对接渠道,连接大模型公司、二手书商和加工工厂,合规开展语料相关对接服务,开拓新的营收增长点。

3. 声誉风险规避:公众对AI破坏文化传承的行为有强烈的负面情绪,平台开展相关业务要兼顾商业利益和公共文化利益,做好公众沟通,避免引发舆论危机,损害平台声誉。

本次曝光的巴拿马计划是AI大模型产业发展中的新动向,对产业研究有重要价值,核心干货如下

1. 产业新动向:大模型训练对语料的需求已经从线上盗版电子书延伸到线下实体书领域,头部企业已经探索出通过购买实体书、扫描后销毁的方式规避版权问题的新模式,这是AI产业发展到大规模训练阶段的新变化。

2. 暴露的新问题:该模式虽然符合现有法律规则,但对文化传承造成了不可逆转的损害,大量孤本、绝版冷门书被永久销毁,破坏了文化多样性,同时也凸显了现有版权法律跟不上AI产业发展的矛盾。

3. 研究启示:研究者需要关注AI发展的伦理和法律问题,推动政策完善,平衡AI产业发展、版权方权益和文化传承三者的关系,探索AI发展过程中保留人文价值的合理路径。

返回默认

声明:快读内容全程由AI生成,请注意甄别信息。如您发现问题,请发送邮件至 run@ebrun.com 。

我是 品牌商 卖家 工厂 服务商 平台商 研究者 帮我再读一遍。

Quick Summary

This article exposes Project Panama, a secret initiative by AI firm Anthropic, and walks through the origins of the event and the reasons behind its widespread controversy. Key takeaways are as follows:

1. Basic event background: Launched in early 2024 with a budget of tens of millions of dollars, Project Panama sees Anthropic purchase millions of physical books published before 2022 in bulk through secondhand booksellers, then scan and destroy all copies. To date, approximately 2 million books have been destroyed. After the project was exposed, it garnered over 2 million views on X (formerly Twitter), with nearly 4,000 critical comments.

2. Core points of controversy: Anthropic’s core goal is to obtain training data for its large language model. By destroying physical copies after scanning, the company exploits a loophole in U.S. law to claim "fair use" of the content. However, the practice damages cultural heritage: most of the destroyed books are rare out-of-print titles with extremely limited circulation. A comparison with Google’s early book-scanning project highlights the erosion of humanistic values amid AI development.

This incident holds multiple key insights for brands operating in AI and cultural content sectors. Key takeaways are as follows:

1. Copyright compliance risk warning: AI copyright disputes have become a pervasive global legal issue. As of May 2026, 112 AI copyright-related lawsuits are pending worldwide, with nearly 80% concentrated in the U.S. Anthropic itself previously paid a $1.5 billion settlement for using pirated e-books to train its models. Brands developing AI businesses must prioritize copyright compliance in advance to avoid the risk of catastrophic compensation.

2. Brand reputation warning: The widespread public outcry over Anthropic’s secret book destruction shows that the public values cultural heritage deeply. Brands pursuing related projects cannot prioritize commercial interests alone; they must account for public cultural sentiment, or risk irreversible damage to their brand reputation.

3. Brand building takeaway: The public recognizes humanistic values in digital transformation. Brands can leverage these values to build goodwill and earn public acceptance.

This incident brings clear opportunities and risk warnings for secondhand booksellers. Key takeaways are as follows:

1. Market opportunity: Large AI model developers have massive bulk purchasing demand for long-tail niche physical books, which typically see extremely low circulation in the secondhand market. Large-volume orders can bring direct economic gains for sellers. Sellers can proactively aggregate scarce resources such as out-of-print academic monographs, local historical archives, and niche technical manuals to match large model firms’ purchasing needs, and open up new revenue streams.

2. Risk warning: The current end use of purchased books—scanning followed by destruction—has already sparked massive public controversy over damage to cultural heritage, and targeted regulation is likely to be introduced in the future. Sellers should closely monitor policy developments, balance commercial gains with industry ethics, and mitigate reputational and regulatory risks.

This incident reveals new commercial opportunities and development insights for book processing and digitalization factories. Key takeaways are as follows:

1. New commercial opportunity: Large AI model firms have strong demand for bulk digitalization of physical books. The full process includes multiple processing steps: hydraulic spine cutting, high-speed scanning, shredding and destruction, etc. Projects with tens of millions of dollars in budget and millions of books to process have already emerged. Relevant factories can develop dedicated business lines to serve large model clients and unlock new growth.

2. Upgrade insight: Unlike traditional library scanning, which requires manual handling of rare old books, this business prioritizes automated processing efficiency and eliminates the need for manual page turning. Factories can upgrade to automated assembly lines to improve large-batch processing capacity and adapt to client requirements.

3. Risk warning: This business is tied to significant cultural controversy. Factories must verify the compliance of orders before accepting them, track future policy changes, and mitigate potential risks.

This incident exposes core pain points and new growth trends in the large AI model industry, offering valuable insights for digital and AI service providers. Key takeaways are as follows:

1. Industry pain point: Large model developers have extremely strong demand for high-quality scarce training data, but copyright compliance remains a persistent industry bottleneck. Traditional licensing models are costly and inefficient, and cannot meet large models’ demand for massive training corpora. The industry urgently needs new compliant solutions.

2. Development trend: Large model firms have already begun bypassing existing online copyright frameworks by obtaining legally compliant data through offline purchases of physical books, followed by scanning and destruction. Demand for bulk digitalization of physical books will continue to grow, opening up considerable market space.

3. Strategic business direction: Service providers can develop targeted automated physical book scanning and processing solutions, or explore legal and compliant training data licensing and trading models to solve industry pain points and unlock new business growth.

This incident offers multiple insights on risk mitigation and business development for platform companies pursuing AI-related business. Key takeaways are as follows:

1. Risk mitigation: Copyright risk is the biggest legal threat to current AI platforms. More than 80% of global AI copyright lawsuits are concentrated in the U.S., and one firm has already paid a $1.5 billion settlement. Platforms developing AI training businesses must build out copyright compliance frameworks in advance to avoid costly compensation lawsuits.

2. Business opportunity: The massive demand for scarce training data from large model firms has created new trading scenarios. Platforms can build matching channels to connect large model developers, secondhand booksellers and processing factories, offer compliant data matching services, and open up new revenue growth.

3. Reputational risk mitigation: The public holds strong negative sentiment toward AI practices that damage cultural heritage. Platforms pursuing related business must balance commercial interests with public cultural interests, maintain transparent public communication, and avoid triggering public relations crises that damage platform reputation.

The exposed Project Panama represents a new development in the large AI model industry, and carries important value for industrial research. Key takeaways are as follows:

1. New industry trend: Demand for training data has expanded from online pirated e-books to offline physical books. Leading industry players have developed a new model to avoid copyright issues by purchasing physical books, scanning them, then destroying the original copies. This is a new change as the AI industry enters the large-scale training phase.

2. New exposed problems: While this model complies with existing law, it causes irreversible damage to cultural heritage: a large number of rare, out-of-print niche titles have been permanently destroyed, undermining cultural diversity. It also highlights the mismatch between existing copyright law and the pace of AI industry development.

3. Research insight: Researchers need to prioritize ethical and legal issues in AI development, push for policy improvements, balance the interests of AI industry growth, copyright holders and cultural heritage preservation, and explore reasonable paths to preserve humanistic values amid AI development.

Disclaimer: The "Quick Summary" content is entirely generated by AI. Please exercise discretion when interpreting the information. For issues or corrections, please email run@ebrun.com .

I am a Brand Seller Factory Service Provider Marketplace Seller Researcher Read it again.

【亿邦原创】近日,Anthropic一项秘密项目"巴拿马计划"(Project Panama)被曝光。

这个自2024年初启动的项目可谓是一个“纸质书毁灭计划”,Anthropic通过Better World Books等二手书商批量采购数百万册2022年前出版的纸质书,用液压切割机切掉书脊、高速扫描后送入粉碎机销毁。该项目预算达数千万美元,截至曝光,累计销毁约200万册实体书。

Anthropic内部文件写道:“巴拿马计划是指我们破坏性扫描世界上所有书籍……我们不希望外界知道我们在做这件事。”

此事一出,外界哗然。X平台浏览量超两千万,骂声近四千条。

为什么这件事是邪恶的?

第一层,Anthropic用未经授权的书籍内容作为大模型训练数据,本身在版权上存在问题。2021年,Anthropic在从LibGen等盗版网站下载了超过700万本盗版电子书用于早期模型训练,这属于明确的版权侵权行为,最终被判赔偿15亿美元和解金。其他大模型公司,OpenAI、Meta还是谷歌,都曾面临与Anthropic类似的指控。截至2026年5月,全球在审AI版权相关诉讼共计112起,近八成集中在美国。

第二层,Anthropic精明地绕过版权问题,直接购买二手书,并在扫描之后完全销毁。美国联邦法院判定该操作属于“合理使用”,理由是“合法购买、仅留一份数字副本、不对外传播”,换句话说,因为纸质书被毁,排除了传播风险,该行为反而变得合法了。

第三层,Anthropic累计销毁的200万册实体书中,不排除有孤本或者绝版书。因为它为了获得稀缺的干净语料,真正买的是长尾的冷门书——学术专著、地方史料、小众技术手册、小语种文献、独立出版社的诗集、绝版多年的非虚构作品。这些书印量小、没电子版、二手市场流通量极少。一位不愿透露姓名的职业书商对媒体表示,虽然大额订单在经济上对他有利,但“我不喜欢这种最终用途,也不喜欢那些不常见的书被打成纸浆”。

Anthropic钻了法律的空子,更对文化传承造成损害。

尤其讽刺的是,操盘巴拿马计划的,正是Google图书项目前负责人汤姆·图尔维(Tom Turvey)。

2002年,Google与密歇根、斯坦福、哈佛、牛津、纽约公共图书馆签约,启动Google Books项目。Google出钱出设备,图书馆出书,扫描完归还,图书馆还获赠一份数字副本。书籍数字版的用途是建全文本索引——用户搜关键词能找到书,但版权书只显示几行片段,公共领域的书才能全本看。到2010年,Google与全球几十家图书馆签约,扫了约2500万册以上,高峰期一周扫几万本。

2011年,Google提出的1.25亿美元和解协议,允许它继续扫描并销售数字版,被法院否决。2013年,Google与作家协会的诉讼中,法院判Google胜诉,理由是"变革性使用"——把书变成可检索的知识地图,对作者和公众都有正向外部性。

但赢了官司之后Google放慢了图书扫描,2015年后大规模图书馆扫描实质停滞,重心转向与出版社谈数字版权。

Google Books项目中有个很有意思的细节。当时Google专门研发了自动扫描设备,用真空吸盘翻页,然后扫描。

但自动翻页一直是难点:薄纸会粘连、旧书装订紧掰不开、脆弱书页一吸就裂。所以相当一部分书,尤其是不耐机器处理的旧书和珍本,是靠人工翻页的。Google在密歇根、斯坦福等合作伙伴那里设有扫描中心,雇佣操作员坐在扫描站前,手动翻页、按下扫描键。

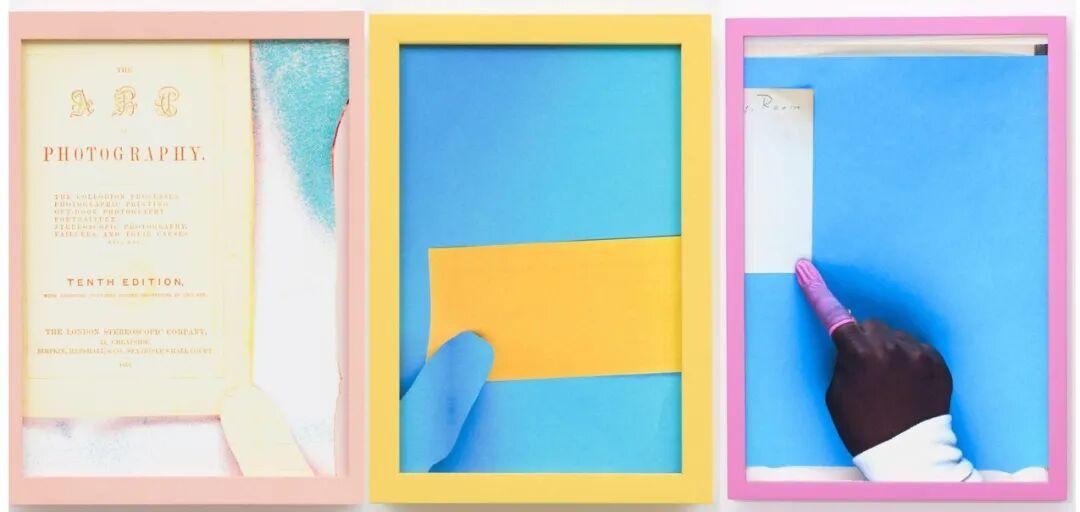
这就导致了一种偶然发生的“故障”情况:翻页者的手还没离开页面、扫描就启动了,操作员的手指、手掌甚至半截小臂就被定格在数字副本里。这些手有胖有瘦,有戴戒指的,有涂指甲油的,年龄肤色各异。

后来有人专门收集了这些"扫描故障"图片,形成一种"故障美学"——大规模工业数字化的过程中,人的痕迹以意外的方式被保留下来。

图片

所以,当我们在Google Books里看到一只手按在书页上时,会想象到这样一个画面:一个具体的人,在一个具体的下午,为这本书翻了一页,这页泛黄的纸张上,还残留着这个人手指的温度。

同时被记录下来的书和人,构成了前现代主义的美感,也与Anthropic二十年后所做之事形成了极致反差。

不知道汤姆·图尔维是不是抱着“终于不用跟这些图书馆、出版社、作者掰扯了,终于不用雇人在扫描机旁翻页了”的轻松心情。

如今的画面变成了这样:旧书摊上一本50年前的技术手册,被运送到Anthropic自动扫描流水线上,被液压切割机切掉书脊,散页送入扫描机,然后进入了粉碎机。这个过程它完全没有接触过、并且再也无法接触到人类的手指。

更可怕的是,这本书的数字化身从此也不可见了,它被AI吞掉、咀嚼、消化、排泄,成为大模型权重里无法识别、无法分离的幽灵。

知识的物理载体被粉碎,数字载体被融化,这是一条单行道,没有回路。

珍惜那只翻书的手。

亿邦持续追踪报道该情报,如想了解更多与本文相关信息,请扫码关注作者微信。

文章来源:亿邦动力

广告
微信
朋友圈

FAQ回顾

Anthropic的巴拿马计划是什么?

巴拿马计划是Anthropic自2024年初启动的项目,预算达数千万美元,通过Better World Books等二手书商批量采购2022年前出版的纸质书,切割书脊完成扫描后销毁,将内容用于AI大模型训练,截至曝光已累计销毁约200万册实体书。

购买二手书扫描后销毁用于AI训练是合法的吗?

美国联邦法院判定该操作属于"合理使用"范畴,理由是合法购买、仅留一份数字副本、不对外传播,纸质书销毁后排除了传播风险,因此该行为具备合法性,但批量销毁可能涉及孤本、绝版书,存在文化传承层面的争议。

AI大模型训练使用书籍内容有哪些版权风险?

若未经授权使用书籍内容作为大模型训练数据属于明确的版权侵权行为,2021年Anthropic曾因从盗版网站下载700万本盗版电子书训练模型,被判赔偿15亿美元和解金,截至2026年5月全球在审AI版权相关诉讼共计112起,近八成集中在美国。

Google Books项目和巴拿马计划有什么核心区别?

Google Books项目扫描书籍后会归还图书馆,数字版用于构建全文检索索引,版权书仅显示片段,具备正向公共价值;巴拿马计划扫描实体书后会直接销毁,书籍数字化内容仅用于AI大模型训练,不对外公开,还可能损害文化传承。

这么好看,分享一下?

朋友圈 分享

APP内打开

+1
+1
微信好友 朋友圈 新浪微博 QQ空间
关闭
收藏成功
发送
/140 0